
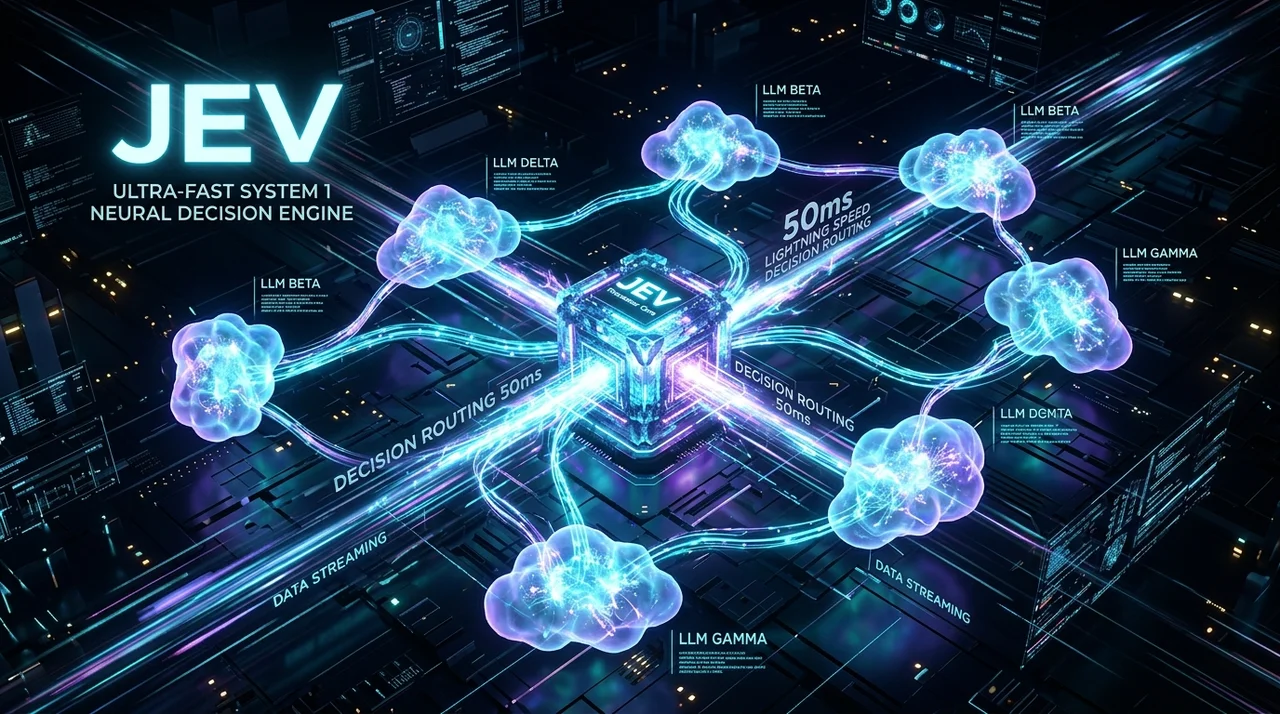
What is Jev and why you should use it
Stop spending tokens on simple yes/no choices. A ~50ms decision model can handle routing for your LLMs and agents without the delay or cost of full token generation.
Drowning in model releases
Every week brings another round of foundation models. New weights drop, context windows get longer, and keeping up with the benchmark charts feels like a full-time job.
Generative models are great for drafting code or explaining tricky concepts. But in production pipelines, we often make a basic mistake: we treat giant autoregressive models as general-purpose routers.
If an agent just needs to pick between two tools or check if an output is valid, sending that prompt to a 70B model means waiting 800ms to two seconds while it streams tokens. That latency adds up fast, and so does the bill.
Jev was built around a simpler premise: split the decision logic from the token generation.
What is Jev?
Jev is a lightweight, non-autoregressive decision model designed to run alongside larger LLMs.
It does not generate text, write code, or create images. Instead, it handles discrete choices. Given an input and a set of candidates, it answers one question: what action should happen next?
flowchart LR
    User([User Request / Event]) --> Jev["Jev Decision Engine\n(~50ms Latency)"]
    Jev -- "Fast Action / Local Tool" --> Exec[Local Tool Execution]
    Jev -- "Complex Generation Required" --> HeavyLLM["Heavy LLM\n(Claude / GPT / Gemini)"]
    Exec --> Output([Result])
    HeavyLLM --> Output
Because it does not predict tokens one word at a time, response times hover around 50 milliseconds. That is fast enough to run locally or inside loops where a normal API call would stall the entire workflow.
Why speed matters: the bullet chess problem
The speed difference is obvious in fast-paced games like bullet chess, where each player gets one to three minutes on the clock for the entire match.
In bullet chess, you do not have time to deliberate. If an engine pauses for two seconds to compose an answer, the clock runs out and the game is over. You need split-second reflexes for every move.
The same constraint applies to real-time systems, whether that is an NPC reacting in a game engine, automated trade guards, or an interface that needs to feel immediate. Autoregressive models are too slow for those tight loops. Jev returns an action in ~50ms, keeping the system responsive under strict time limits.
Running agents without the latency tax
As I shared in my previous piece on developer workflows and AI, staying in control of application architecture means using AI intentionally rather than blindly throwing prompts at problems.
When you coordinate multi-agent setups with systems like Hermes, Claude, Codex, or Antigravity, you quickly notice that most agent steps are not actually creative. They are administrative:
- Did the bash command succeed?
- Does this request need database access or web search?
- Should the output go back to the user or to another agent?
Calling a full frontier model just to classify a status or pick the next tool creates unnecessary latency and burns through token budgets.
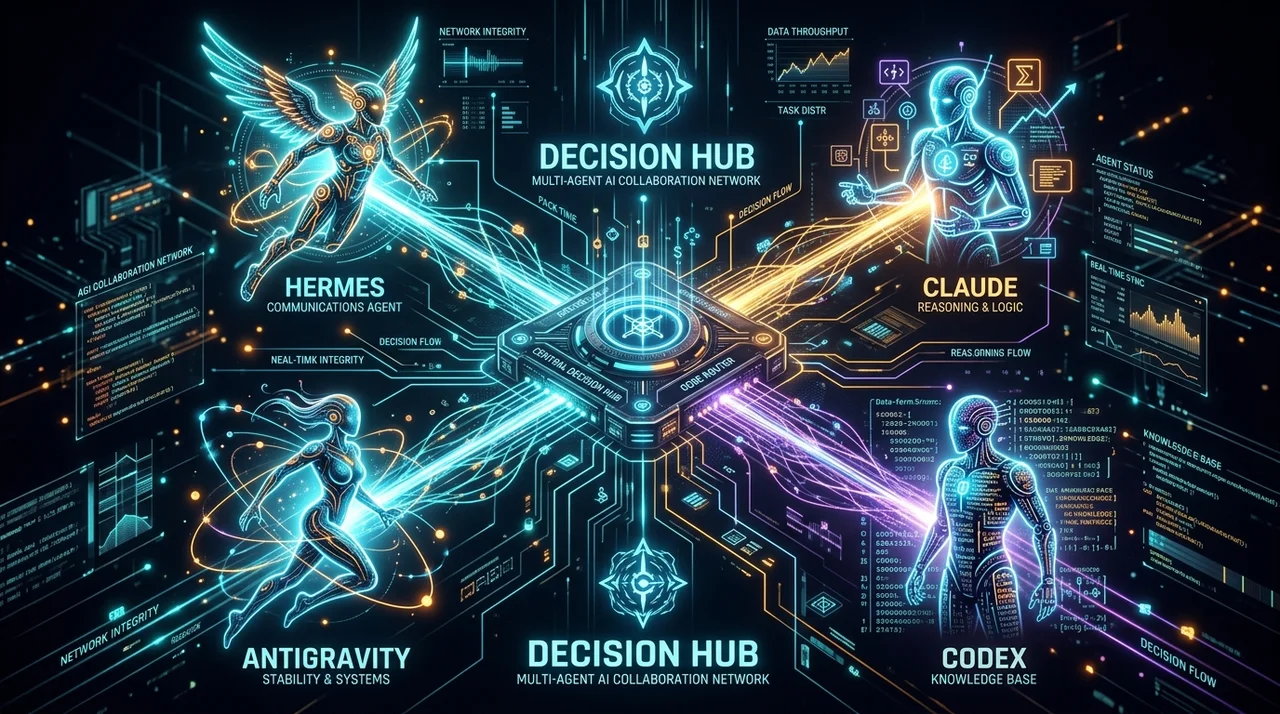
Plugging Jev into an agent architecture changes that flow:
- Lower latency: Routine branching happens in ~50ms instead of two seconds.
- Lower cost: You only call models like Claude or Codex when you actually need text or code written.
- Deterministic routing: Because Jev is a classifier rather than a text generator, you avoid parsing errors, broken JSON, or hallucinated function names.
Comparing generative LLMs and Jev
| Attribute | Generative LLMs | Jev Decision Engine |
|---|---|---|
| Main task | Text and code generation | Classification and action routing |
| Typical response time | 800ms to 3,000ms | Around 30ms to 50ms |
| Output format | String of generated tokens | Discrete action or class index |
| Hardware demand | High GPU memory | Lightweight (runs easily on CPU) |
| Cost profile | Per-token API pricing | Negligible per-request overhead |
| Hallucination risk | Requires guardrails | None on route selection |
Example integration
Here is a practical way to place Jev in front of a standard LLM call:
from jev import DecisionEngine
from anthropic import Anthropic

jev = DecisionEngine(model="jev-fast-v1")
claude = Anthropic()

def handle_request(user_input: str):
    # Step 1: Fast routing check (~50ms)
    decision = jev.decide(
        input=user_input,
        options=["cached_response", "direct_sql_query", "deep_llm_reasoning"]
    )

    # Step 2: Act on the route
    if decision.action == "cached_response":
        return get_cache(user_input)

    if decision.action == "direct_sql_query":
        return query_db(decision.params)

    # Only invoke the heavy model when text synthesis is genuinely needed
    return claude.messages.create(
        model="claude-3-7-sonnet",
        prompt=user_input
    )
In this setup, the heavy model is never the default gatekeeper. Jev evaluates the input first, dispatches routine tasks immediately, and passes through only the requests that require actual generative work.
Summary
Not every step in an AI pipeline requires a hundreds-of-billions parameter model. When you separate routine decision routing from text generation, you cut latency, eliminate token waste, and keep multi-agent systems responsive.
Comments
Leave a comment